ComboGAN : Image Translation with GAN (7)
arixv: ComboGAN: Unrestrained Scalability for Image Domain Translation
accpeted to ICLR2018 workshop
reddit
github
Scalibility issue for multi domains
CycleGAN : Two-domain models taking days to train on current hardware, the number of domains quickly becomes limited by the time and resources required to process them.
Propose a multi-component image translation model and training scheme which scales linearly - both in resource consumption and time required - with the number of domains.
Difference with StarGAN
So StarGAN uses a single generator and a single discriminator, which is adequate when the domains are actually slight variations of each other, such as human faces with different hair colors or smiles, as a shared network can potentially make use of common features. During the course of our own trial-and-error, we found using a StarGAN-like approach starts to break down when the domains are not so similar.
ComboGAN increases the number of model parameters as more domains are added, thus being able to scale up a large number of domains, at which StarGAN could be constrained by the one-model setup.
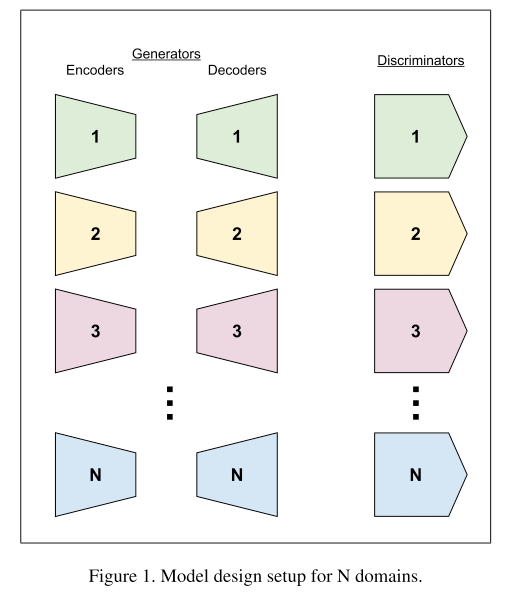
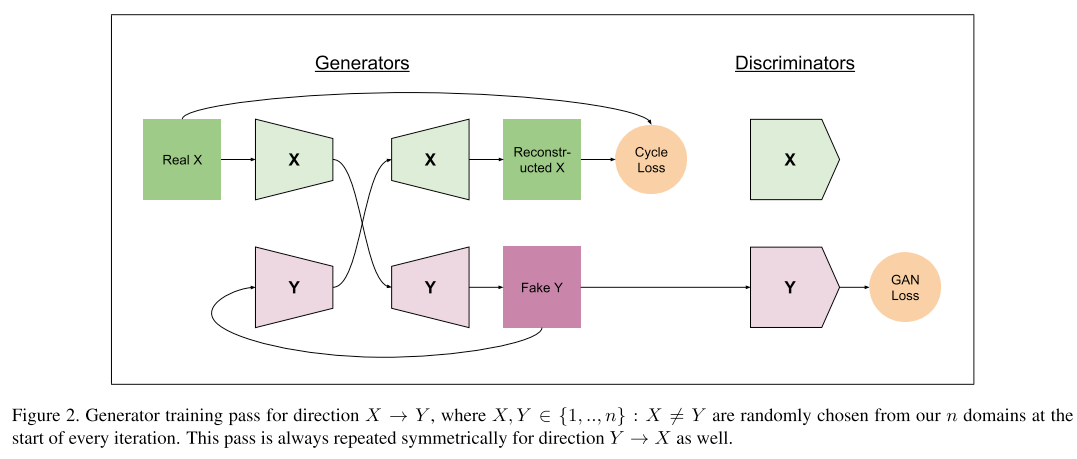

Decouple Generator. $y=G_{YX}(x)=Decoder_Y(Encoder_X(x))$
$Encoder_X(x)$ can be cached
One generator per domain, linearly increase. with $n$-domains, CycleGAN : $n(n-1)$ Generators needed, ComboGAN : $n$ Generators.
Training iterations, model capacity also reduces.
the # of Discrimitors are same as CycleGAN. In the case of more than two domains, the encoder output has to be suitable for all other decoders, meaning encoders cannot specialize.
Implies the encoders must put image into shared representation. Encoder sould make central content. (similar to my work PaletteNet)
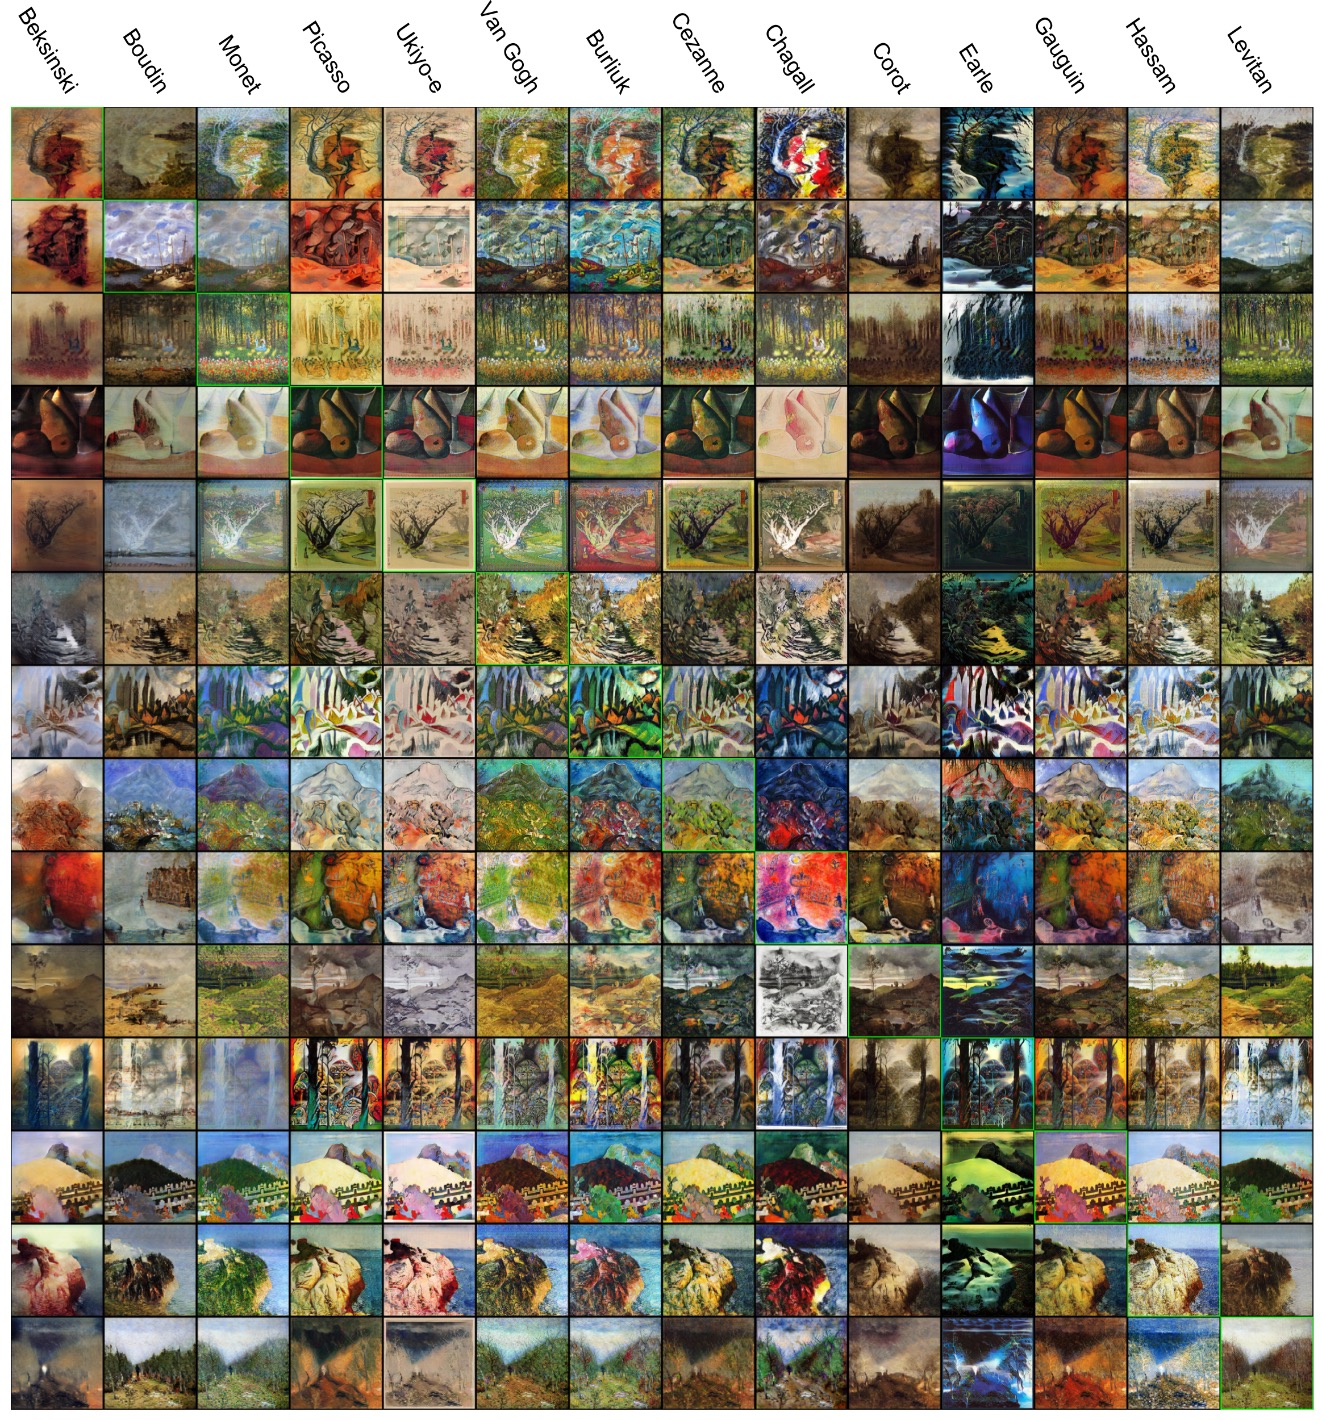
Results