CycleGAN : Image Translation with GAN (4)

Share
CycleGAN : Image Translation with GAN (4)
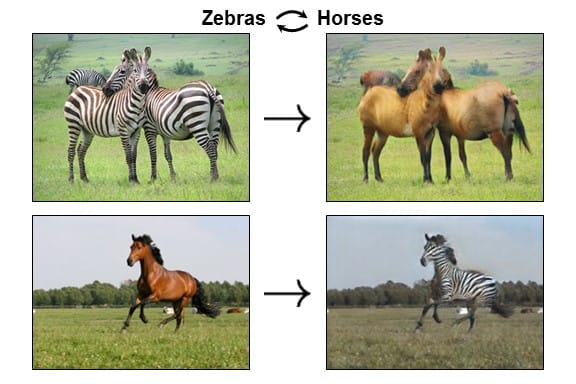
Unpaired Image-to-Image Translation using Cycle-Consistent Adversarial Networks (CycleGAN) from UC Berkeley (pix2pix upgrade)

&

Learning to Discover Cross-Domain Relations with Generative Adversarial Networks (DiscoGAN) from SK T-Brain

DiscoGAN & CycleGAN

  • Almost Identical concept.
  • DiscoGAN came 15 days earlier. Low resolution ($64 \times 64$)
  • CycleGAN has better qualitative results ($256 \times 256$) and quantative experiments.

Difference from DTN

  • No $f$-constancy. Do not need pre-trained context encoder
  • Only need dataset $S$ and $T$ by proposing cycle-consistency

DiscoGAN
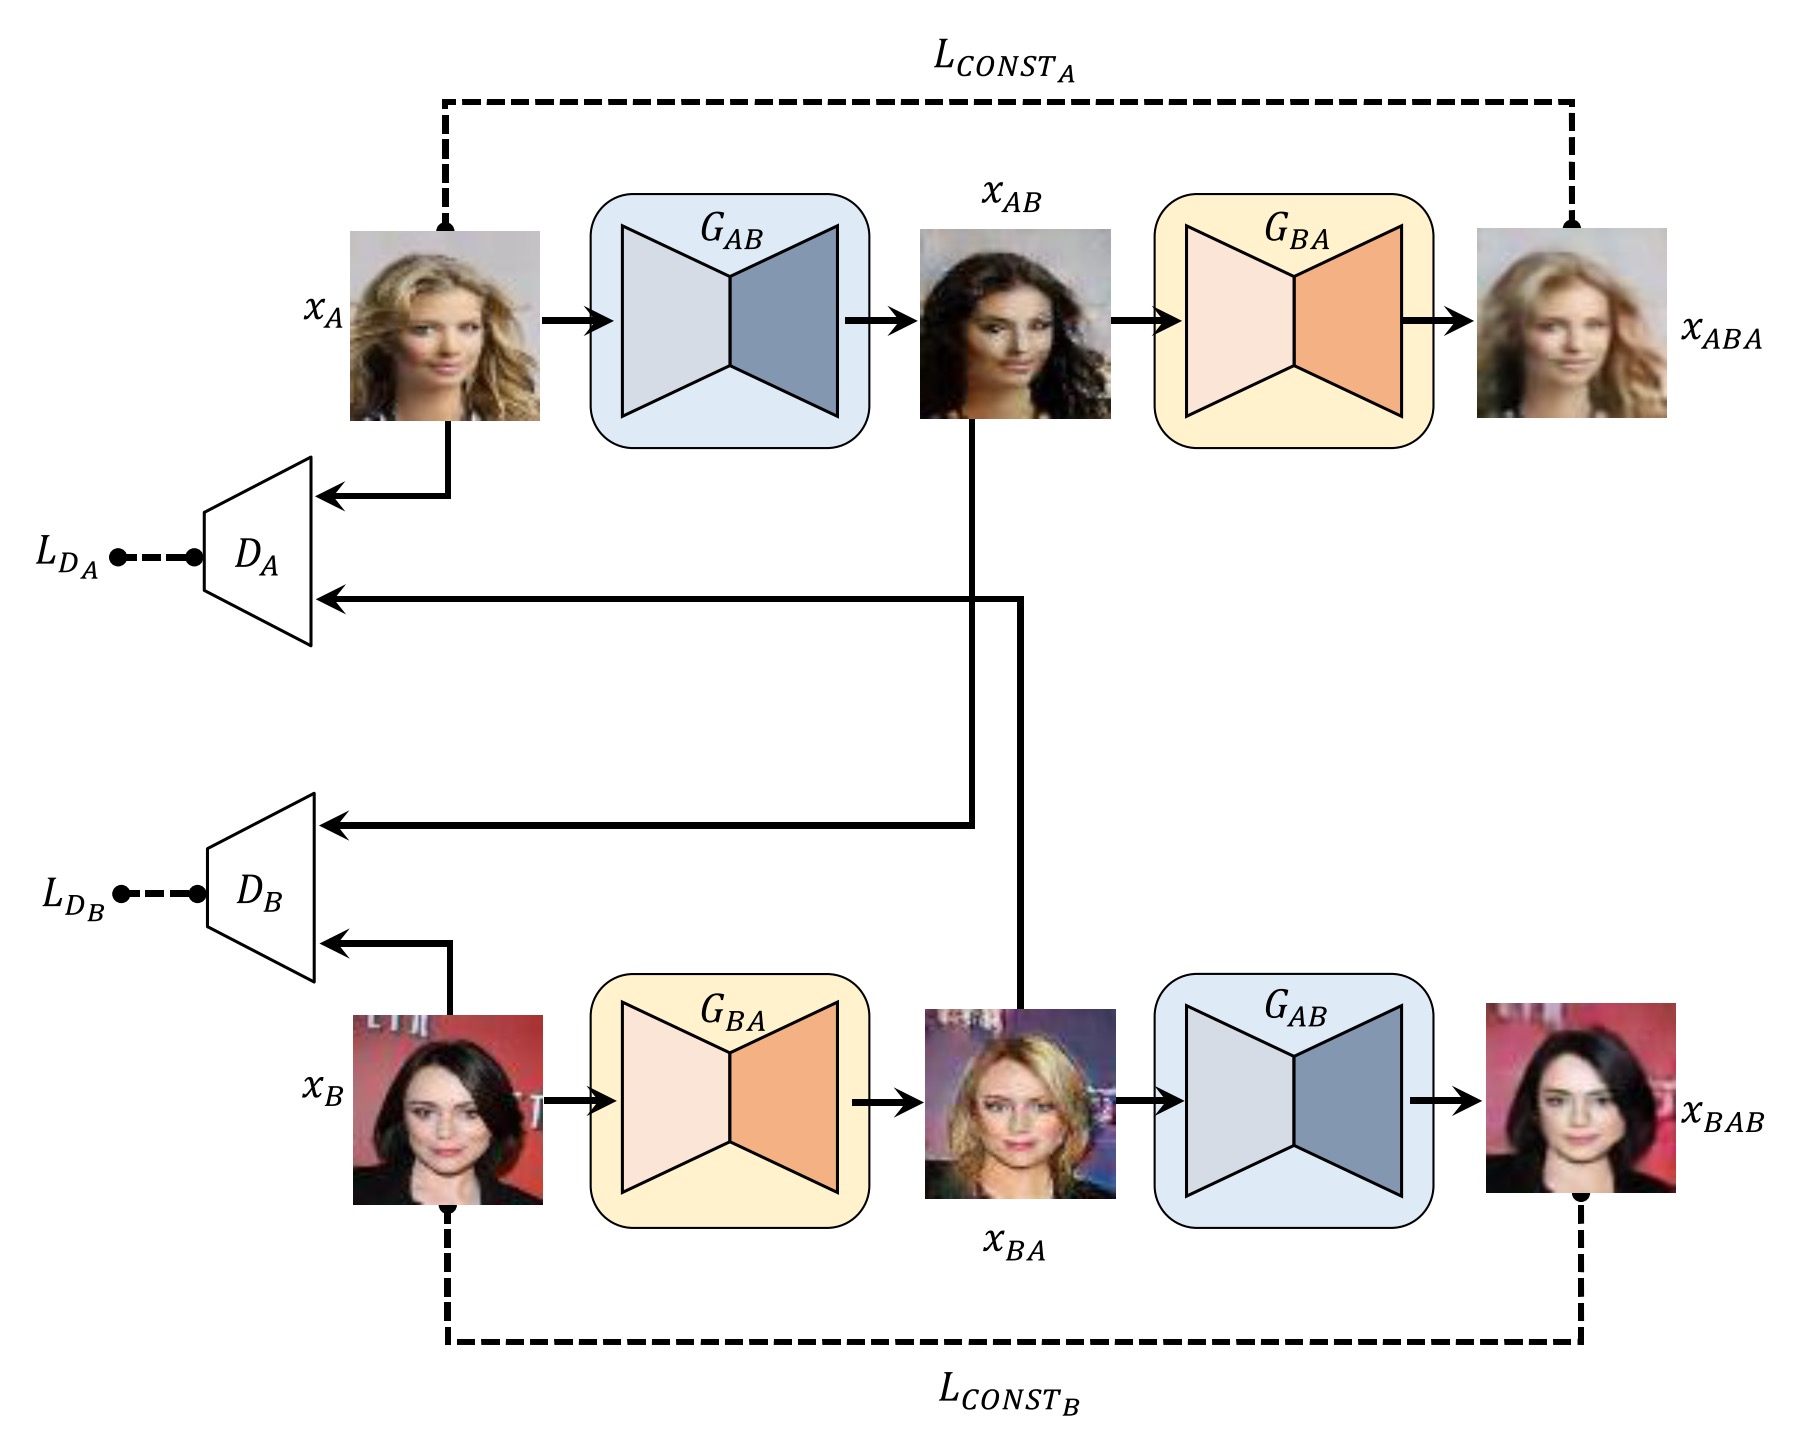
right fit

inline

without cross domain matching, GAN has mode collapse

inline

learn projection to mode in domain $B$, while two domains have one-to-one relation

Typical GAN issue: Mode collapse

inlineinline

  • top is ideal case, bottom is mode collapse failure case
  • Toy problem of 2-dim Gaussian mixture model
  • 5 modes of domain A to 10 modes of domain B

inline

  • GAN, GAN + const show injective mapping & mode collapse
  • DiscoGAN shows bijective mapping & generate all 10 modes of B.

proposed DiscoGAN
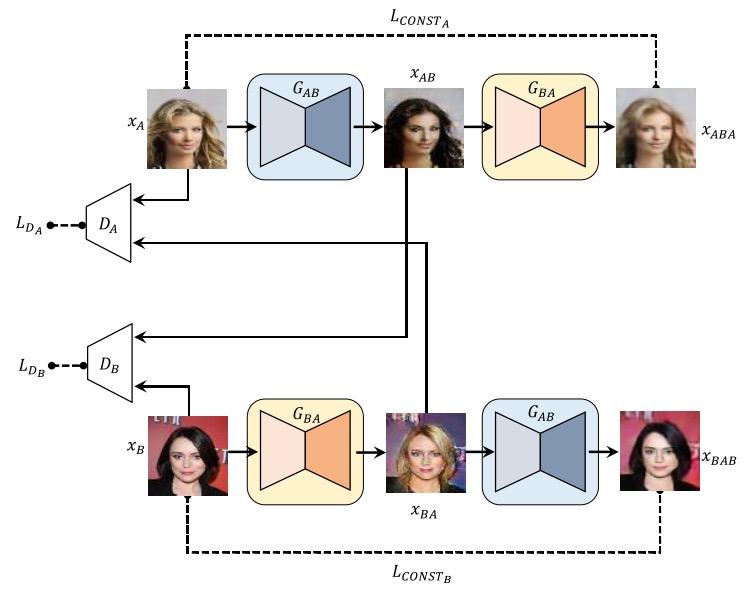
inline

CycleGAN has similar contribution on this point

inline
inline

Results

inline
inline

codes and more results in

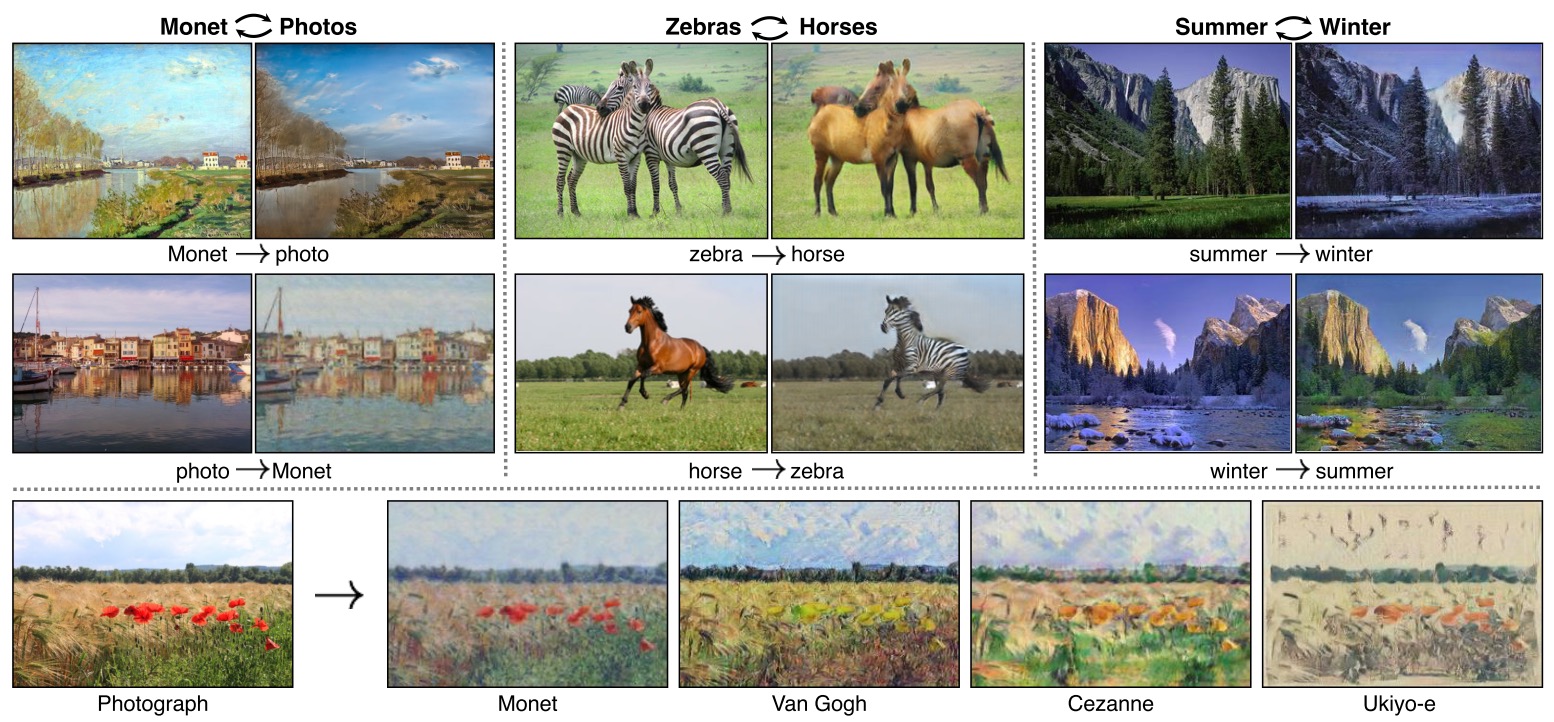
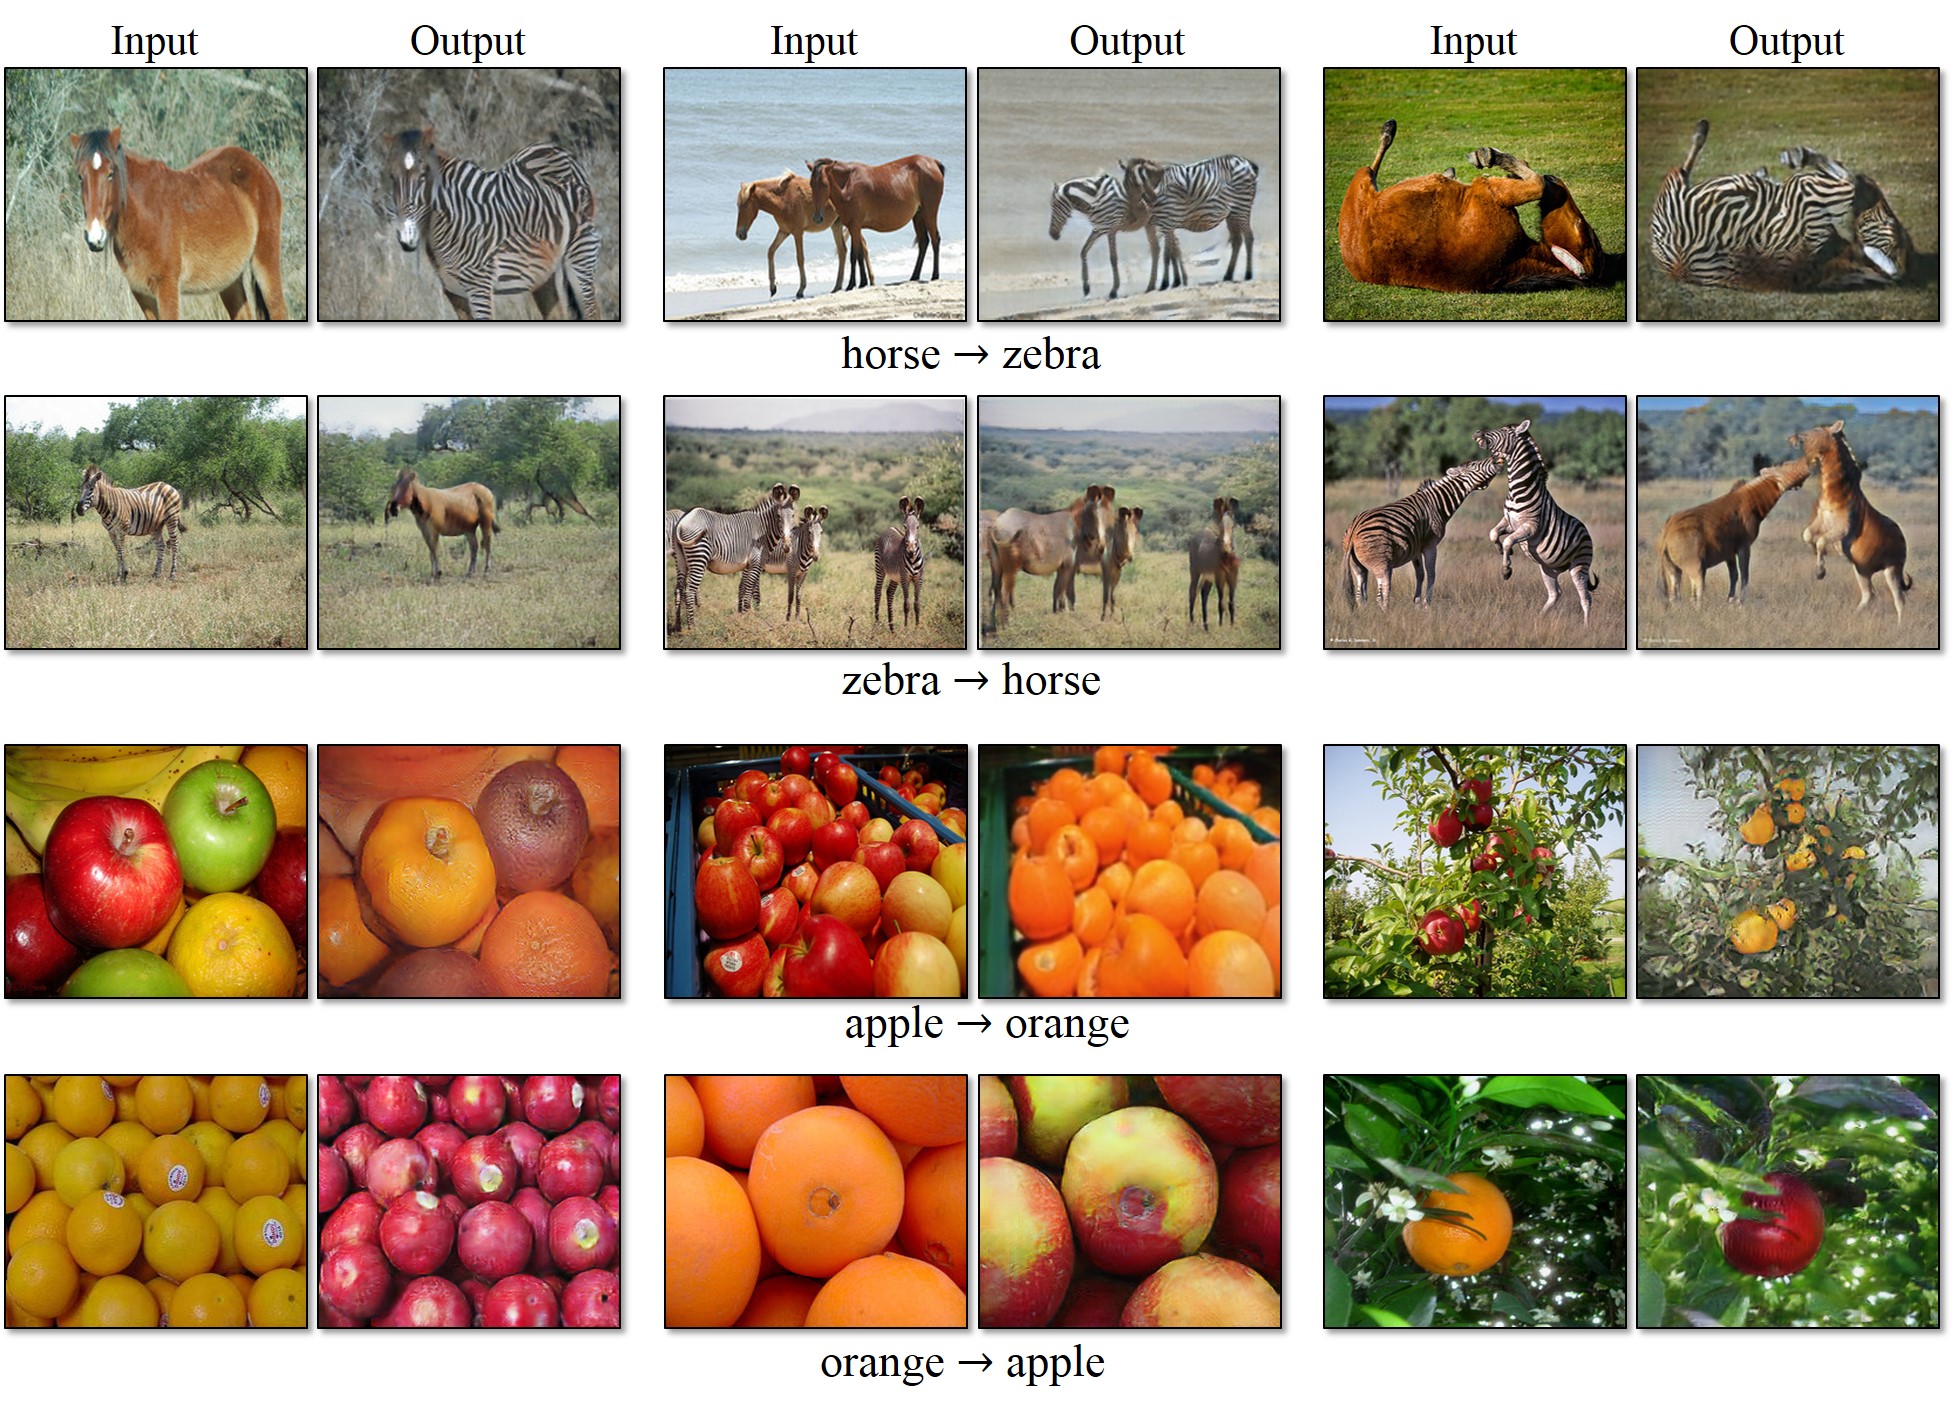
CycleGAN

inline

Use more GAN techniques: LSGAN, use image buffer of previous generated samples
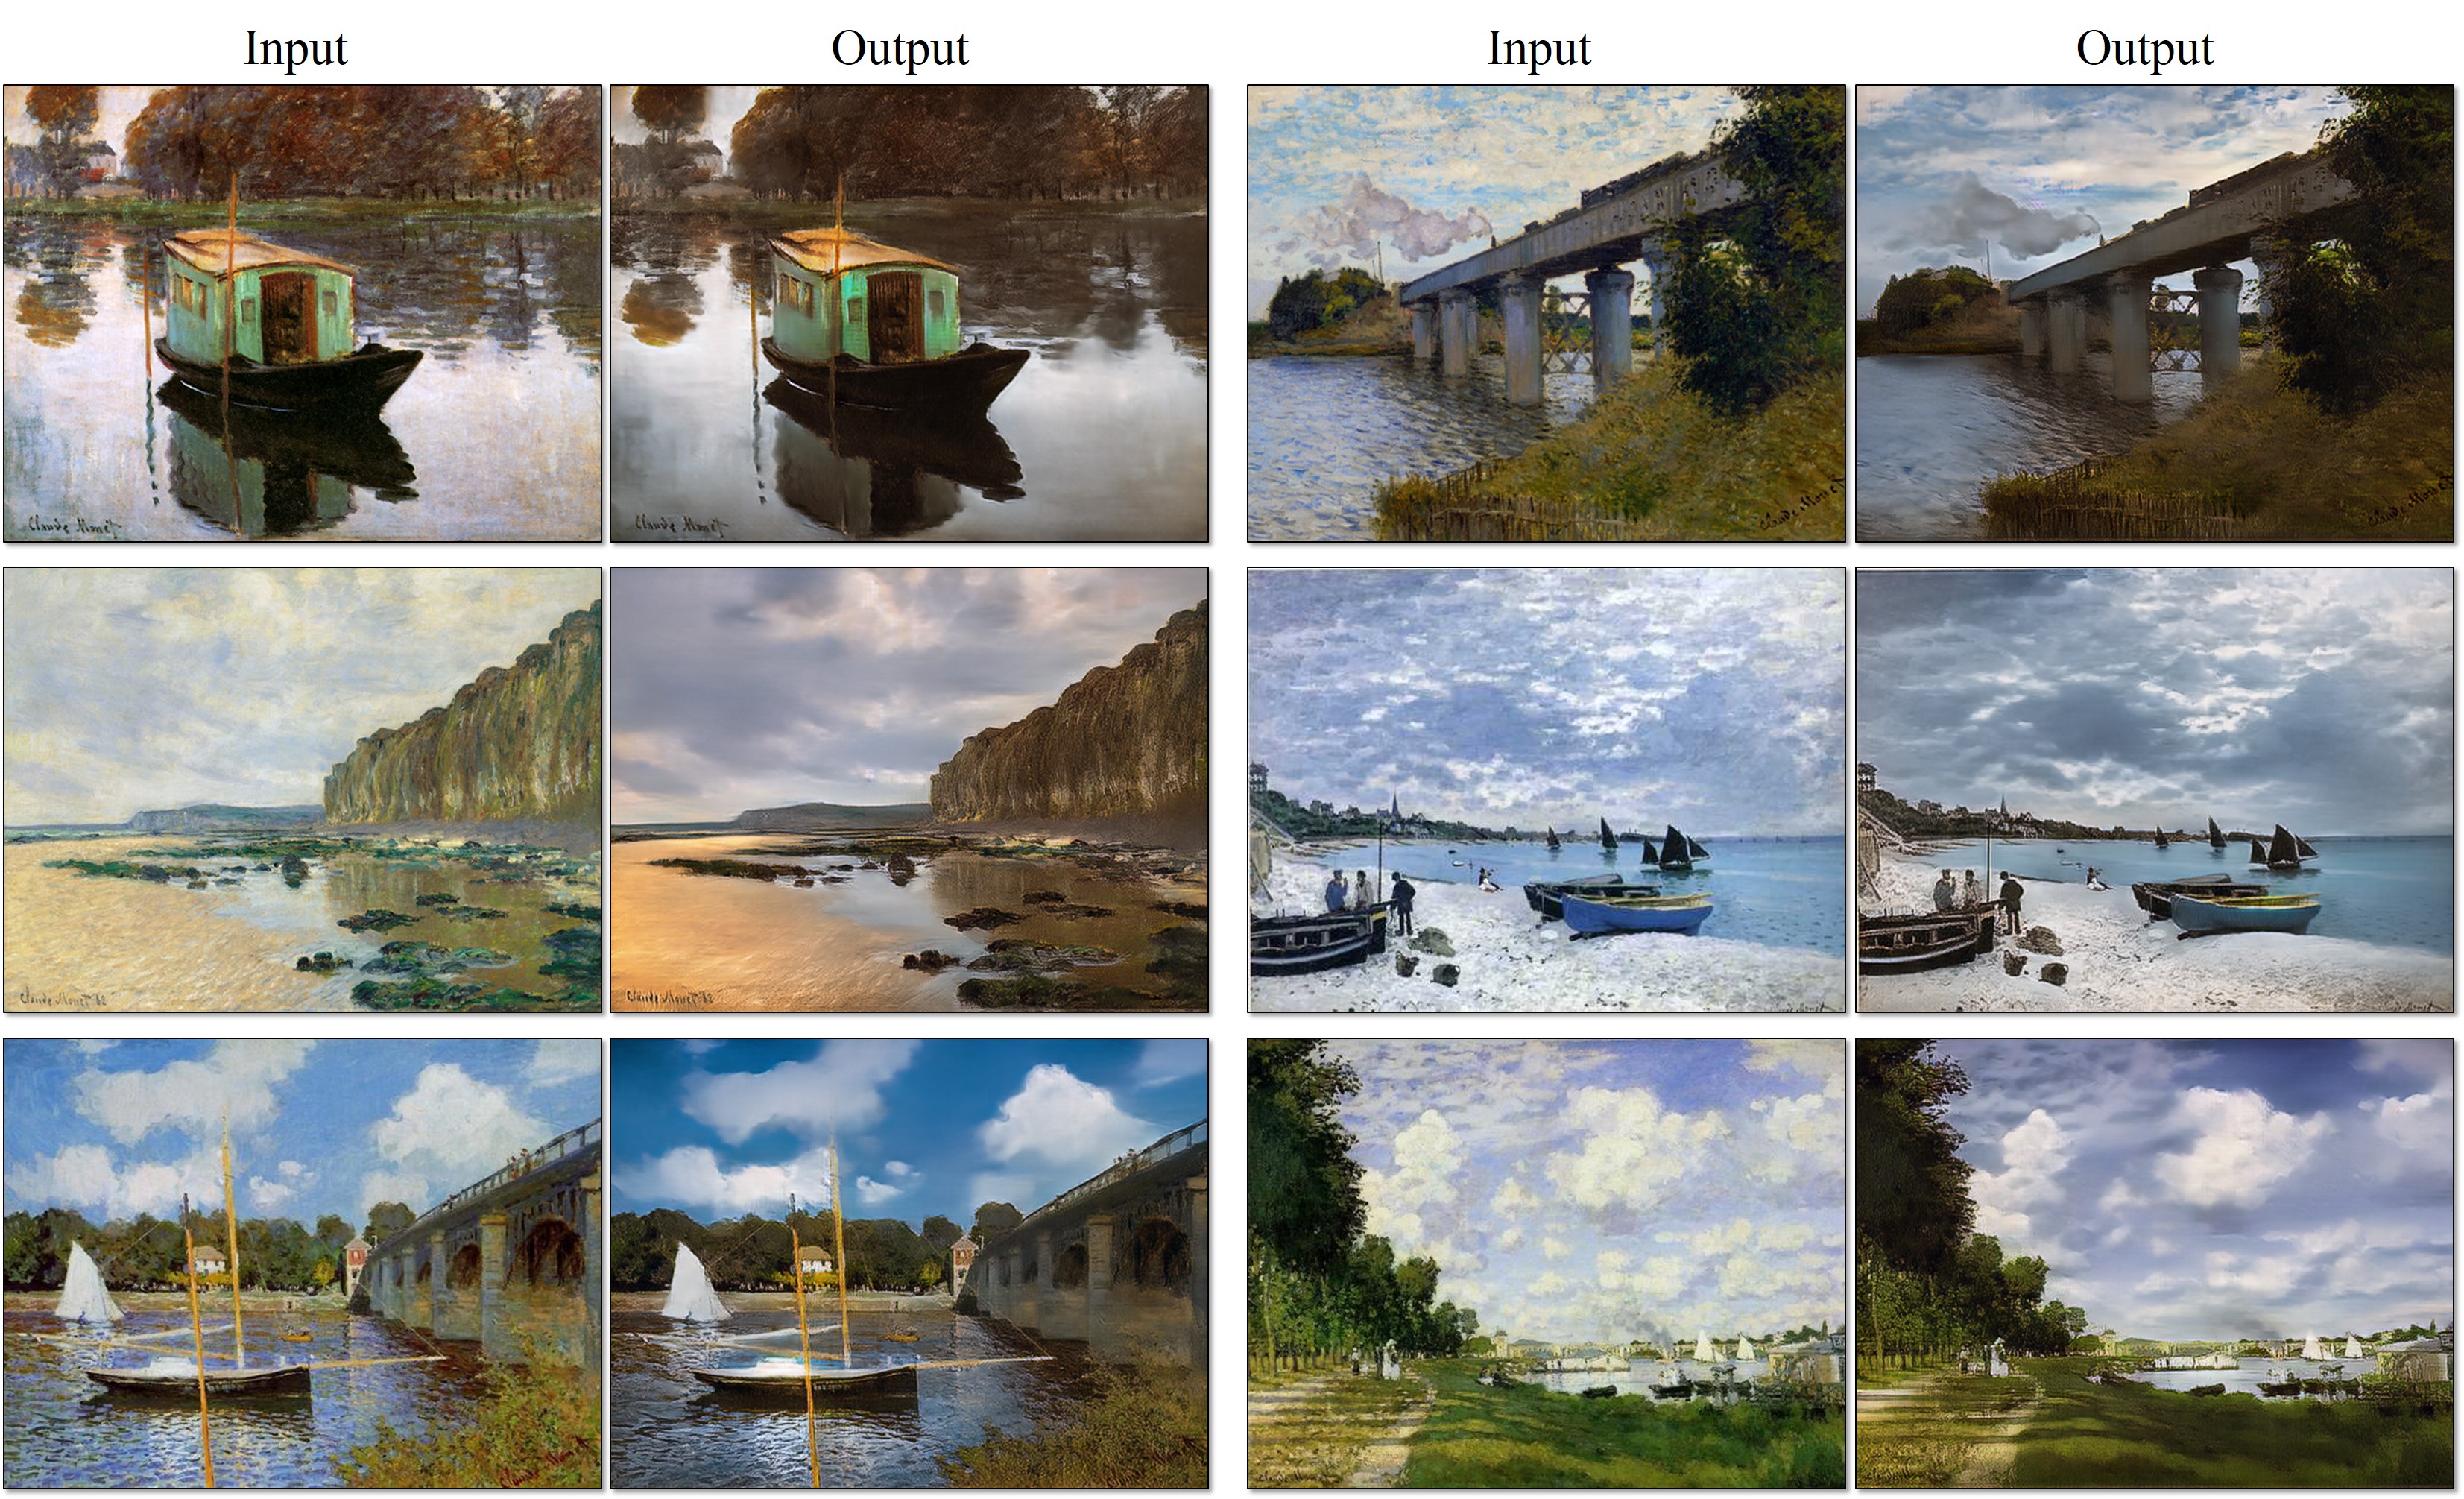
inline
inline
inline
inline
inline

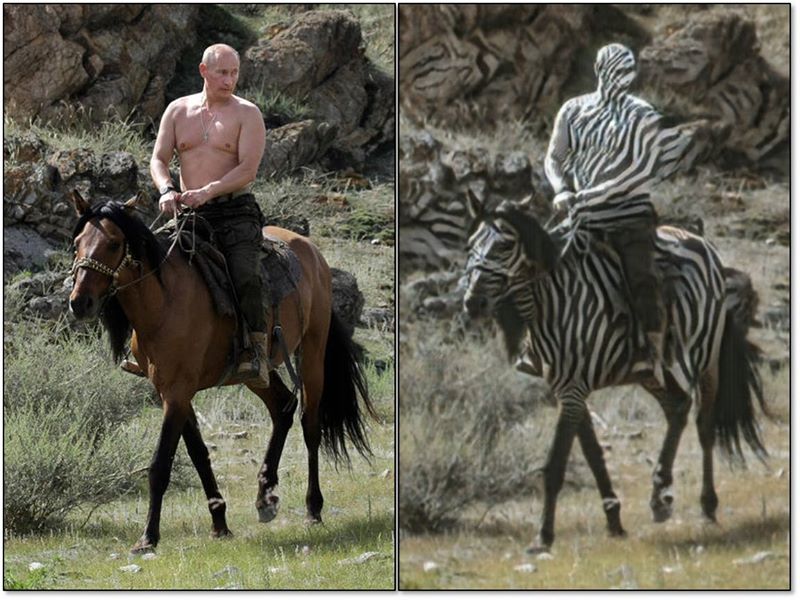
failure case

inline

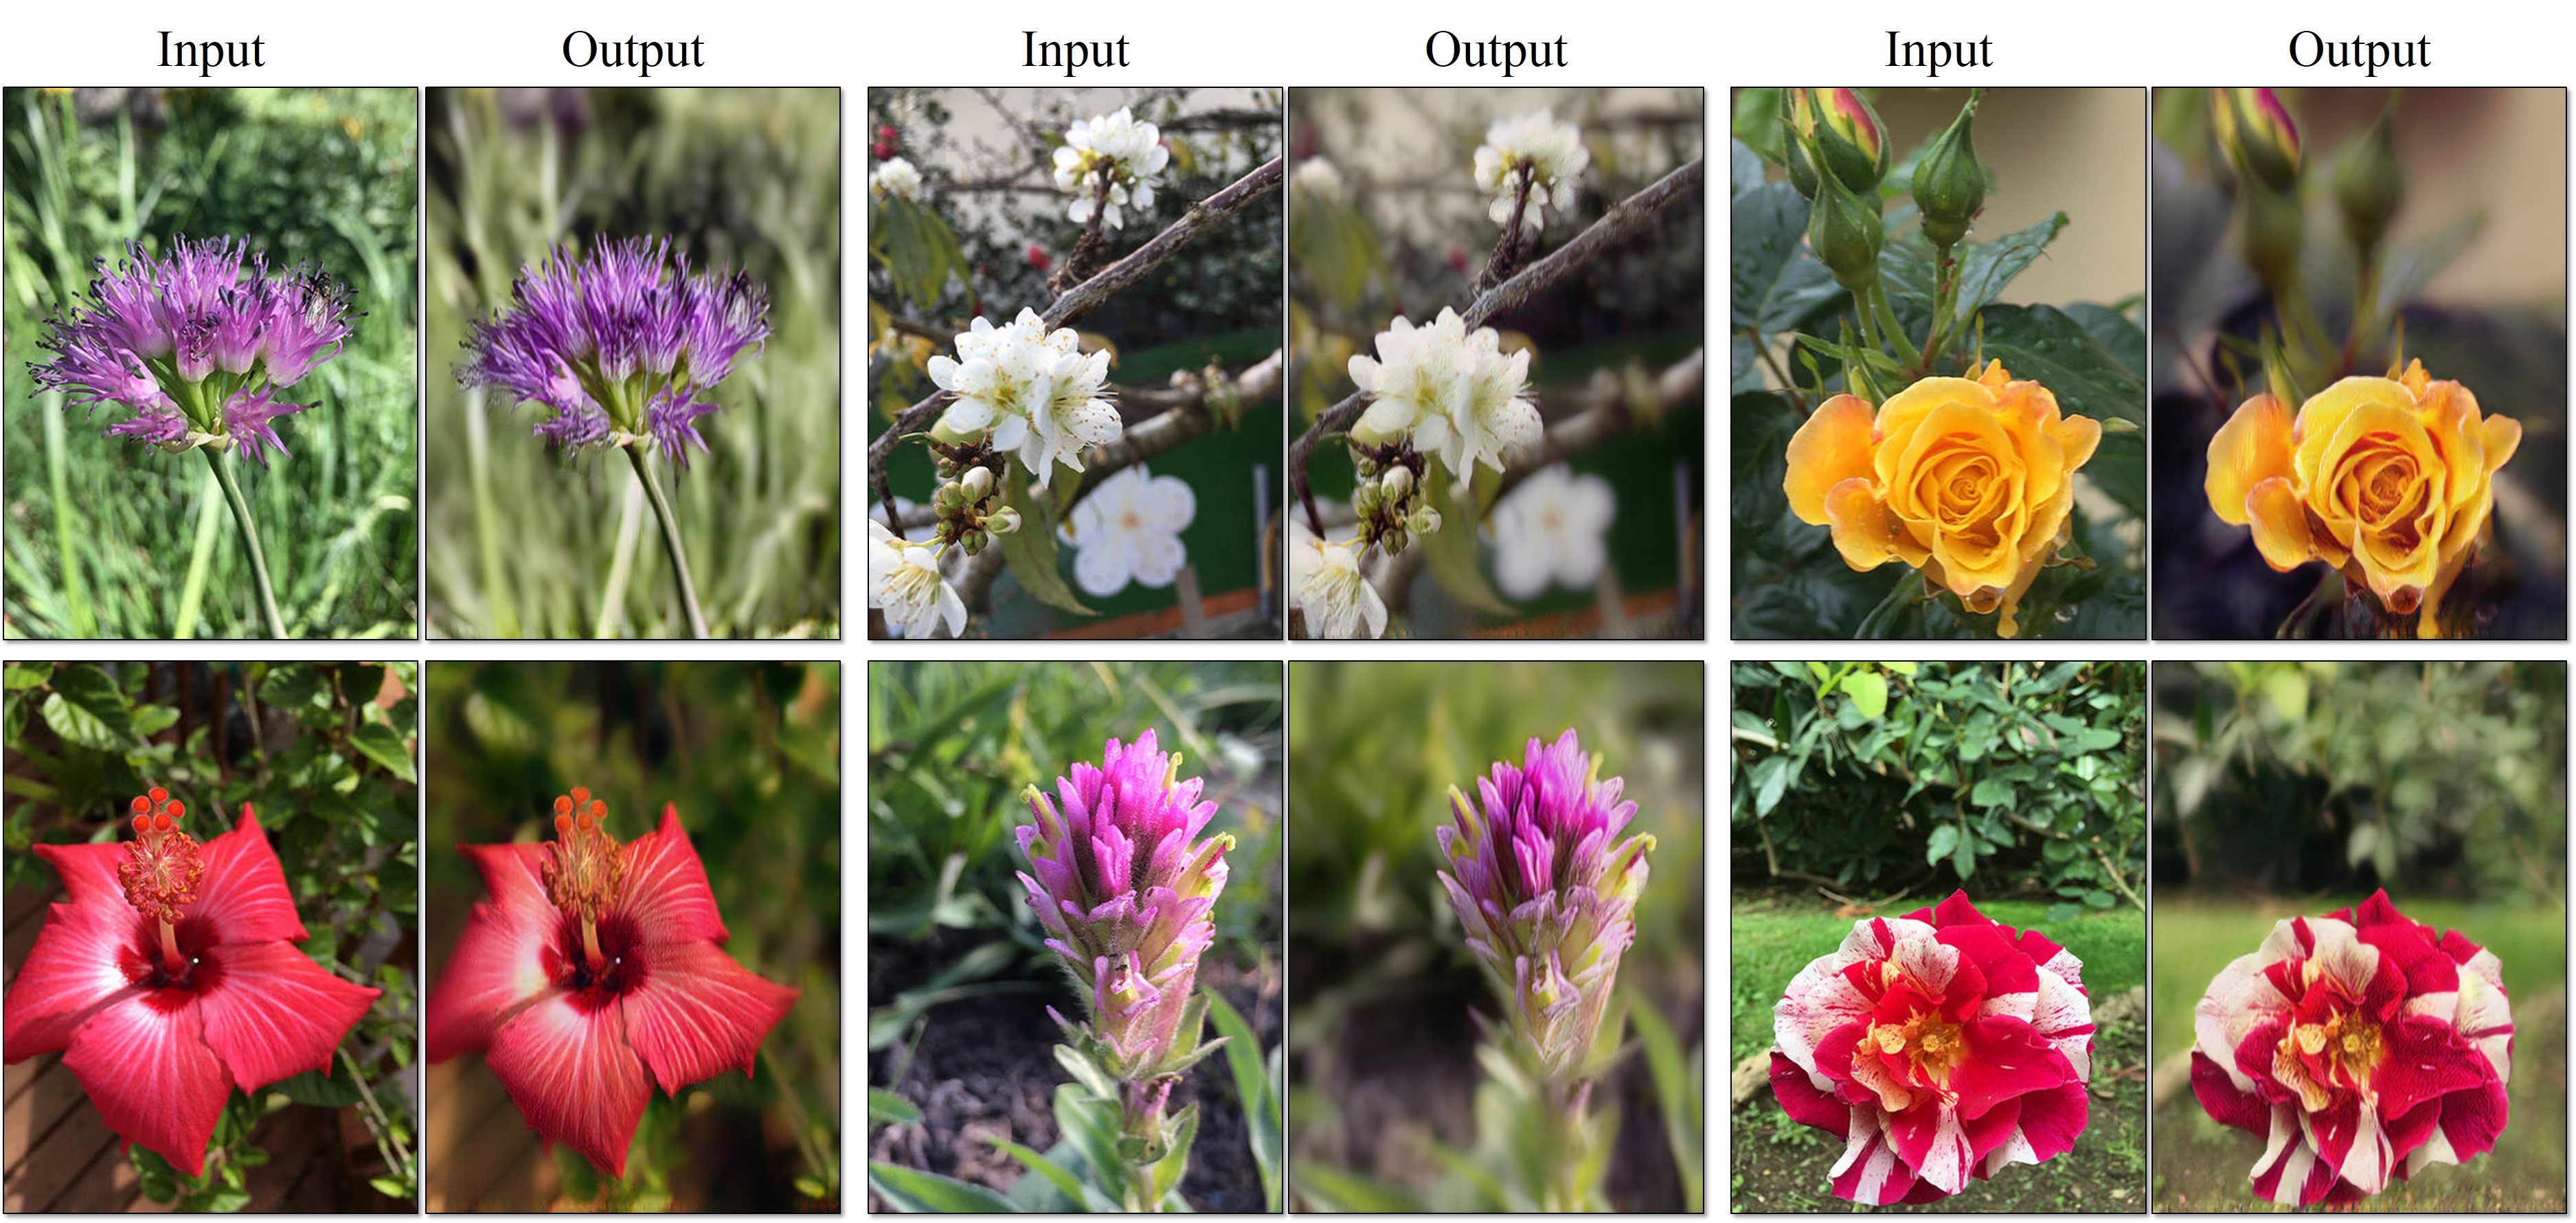
CycleGAN demonstrates more experiments!
project page : https://junyanz.github.io/CycleGAN/
code available with Torch and PyTorch

Read more

허깅페이스 르로봇 해커톤 후기

허깅페이스 르로봇 해커톤 후기

본 블로그의 주인장들은 이번 허깅페이스의 르로봇 월드와이드 해커톤의 서울 호스트를 맡았습니다. 너무 재밌었고, 그 과정들과 후기를 남깁니다. 현장은 다큐 형식의 작은 영상을 만들었으니 한번 봐주세요. 계기 저는 LLM 만 하고 있었고, Action 모델은 사실 관심이 없었습니다, 준호는 1년 정도 로봇에 AI 를 넣는 일을 하고 있었죠. 허깅페이스에서 르로봇 플랫폼을 만들고

By park jong hyun
DeepDive LLM 3편 - Reinforcement Learning

DeepDive LLM 3편 - Reinforcement Learning

* 1편 - 사전 학습 (Pre Training) * 2편 - Supervised Fine Tuning * 3편 - Reinforcement Learning Reinforcement Learning Pretrain, SFT 에 이어서 세번째 단계는 Reinforcement Learning (RL, 강화학습) 입니다. 비유를 해보자면, pretrain은 그냥 책을 읽는 것이고요, SFT는 예제 문제와 이미 작성된 해설을 보는 것입니다. RL 은 해설이 없는 문제를 직접 풀어보는 것입니다. 어떻게 풀든

By park jong hyun
DeepDive LLM 2편 - Supervised Fine Tuning

DeepDive LLM 2편 - Supervised Fine Tuning

* 1편 - 사전 학습 (Pre Training) * 2편 - Supervised Fine Tuning * 3편 - 강화 학습 (Reinforcement Learning) Supervised Fine Tuning Post Training 의 첫번째 단계 SFT 입니다. Pre Training 에 비하면 아주 작은 양의 데이터만 필요하지만, 실제로 성능을 이끌어 내는데에는 중요한 단계입니다. 멀티턴 대화 (Multi Turn Conversation) ChatGPT 를 포함해서 대부분의 AI 서비스들은

By park jong hyun
DeepDive LLM 1편 - 사전 학습 (Pre-Training)

DeepDive LLM 1편 - 사전 학습 (Pre-Training)

본 포스트 시리즈는 카파시 선생님의 영상 을 기반으로 정리한 내용입니다. 직접 유투브에서 다루기도 했으니 영상으로 보셔도 됩니다. * 1편 - 사전 학습 (Pre-Training) * 2편 - Supervised Fine Tuning * 3편 - 강화 학습 (Reinforcement Learning) LLM 의 Training LLM을 만들 때는 크게 세 가지 주요 단계가 있습니다. 1. 사전 학습(Pre-Training) * 인터넷 텍스트(

By park jong hyun